Cut Incident Time: Logs, Metrics, and Traces for SREs (30/90/180 Plan)
Cut Incident Time: Logs, Metrics, and Traces for SREs (30/90/180 Plan)
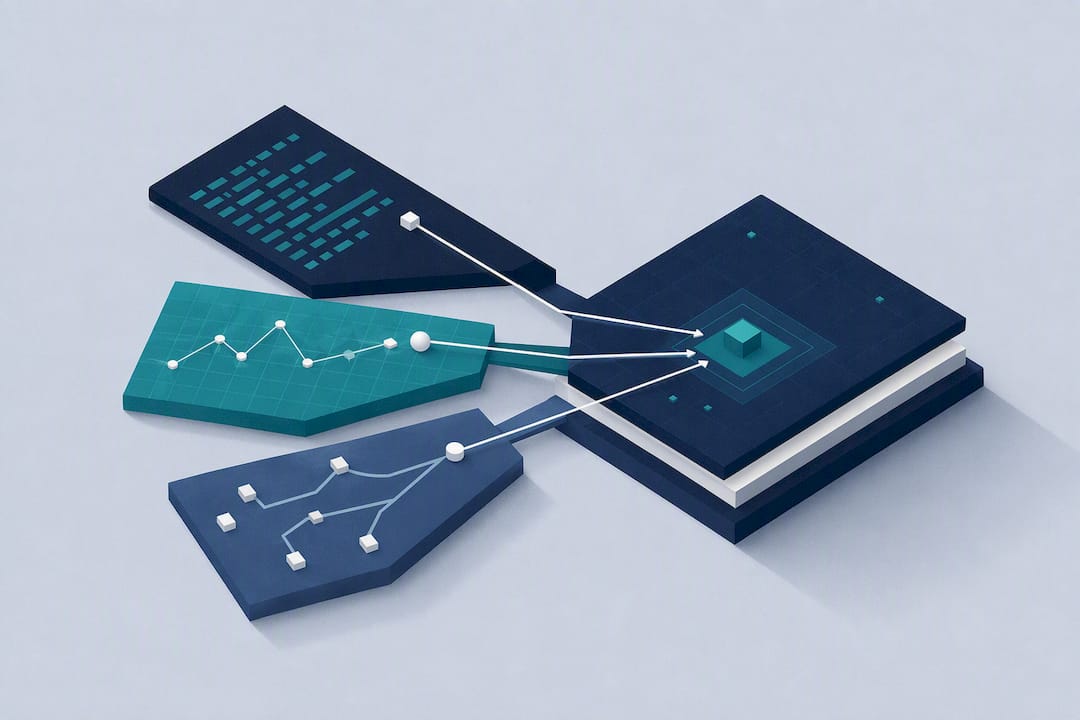
Metrics show trends and trigger alerts, traces show where a request spent its time, and logs record the detailed why behind a failure. The practical order for most teams: instrument metrics and structured logs first, then add distributed tracing once requests start crossing service boundaries. If you only do one thing this week, add a trace_id field to every log line your critical services emit and start counting error_rate and latency as real metrics.
TL;DR:
- Adding a trace ID to every critical log line significantly improves correlation and debugging across services without requiring full tracing infrastructure.
- Metrics, especially counters, gauges, and histograms, offer a low-cost way to monitor trends and identify issues before investigation, but they should be carefully labeled to avoid cardinality explosion.
- Structured logs with standardized fields enable faster root cause analysis by allowing filtering based on timestamp, service, trace ID, and log level, especially during incidents.
- Traces provide end-to-end request flow visibility and are most valuable for diagnosing latency issues and dependency failures when sampling is implemented to control overhead.
- Implementing a phased approach—first instrument metrics and logs, then add tracing, and finally establish SLOs—helps teams build comprehensive observability without overwhelming infrastructure costs.
Table of Contents
- What Metrics Are: Types, Labels, and Primary Uses
- What Logs Are: Structured Events, Levels, and Why Structure Matters
- What Traces Are: Spans, the Waterfall, and Tracing Use Cases
- Logs, Metrics, and Traces Side by Side
- How Logs, Metrics, and Traces Work Together
- When to Reach for Each Signal
- Implementation Considerations: Instrumentation, Storage, and Cost
- A 30/90/180-Day Roadmap to Working Observability
- Correlate Every Signal in One Place With Opsphere
- Sources
- FAQ
What Metrics Are: Types, Labels, and Primary Uses
A metric is a number sampled over time. That simplicity is the whole point: metrics compress into labeled time series that scale cheaply, which is why they’re the workhorse for alerts, dashboards, and long-term trend analysis. You don’t store every request. You store aggregates, and aggregates are fast to query even at high volume.
Three shapes cover most use cases:
- Counters only go up. Use them for
request_countorerror_count. - Gauges move up and down. Use them for
queue_depthoractive_connections. - Histograms bucket values into distributions. Use them for
latency, so you can computep95orp99instead of a misleading average.
Labels turn a raw counter into something queryable, like error_rate{service="checkout", region="us-east", status="500"}. The trap is uncontrolled label values. Adding a customer ID or a raw URL path as a label multiplies the number of unique time series, and that cardinality explosion is what actually blows up your metrics backend’s storage and query latency, not the metric count itself. Metrics are also what SLOs run on: an SLO defines a target (99.9% of requests under 300ms), and a metric like latency_p95 is what your alerting engine checks against it every minute.
What Logs Are: Structured Events, Levels, and Why Structure Matters
A log is a timestamped record of a single event, and it’s the signal built to answer “why did this happen,” carrying the stack traces and input/output detail that metrics and traces can’t hold. Free-text logs work until you need to search them at 2 AM during an incident. Structured JSON logs solve that by standardizing fields so every entry is machine-parseable.
At minimum, standardize on:
timestampin a consistent format across every serviceservicename, matching what you use in traces and dashboardstrace_id, so a log line can be pivoted to a tracelevel(ERROR, WARN, INFO, DEBUG)messageand, for failures, theerrorobject with a stack trace
Log levels aren’t decoration. ERROR means an unhandled failure that needs attention. WARN means something recoverable happened, like a retry succeeding on the second attempt. INFO covers normal operational events (a deploy started, a job finished). DEBUG and TRACE are for diagnostics you’d only enable while actively investigating something, since logging every function call in production gets expensive fast.
Pro Tip: Redact sensitive fields (tokens, PII) at the point of emission, not after ingestion. It’s far cheaper to scrub one log statement than to audit a year of retained data later.
Retention is a cost lever, not just a compliance one. Keep ERROR and WARN logs longer than INFO, and consider shorter retention windows for high-volume, low-value DEBUG output.
What Traces Are: Spans, the Waterfall, and Tracing Use Cases
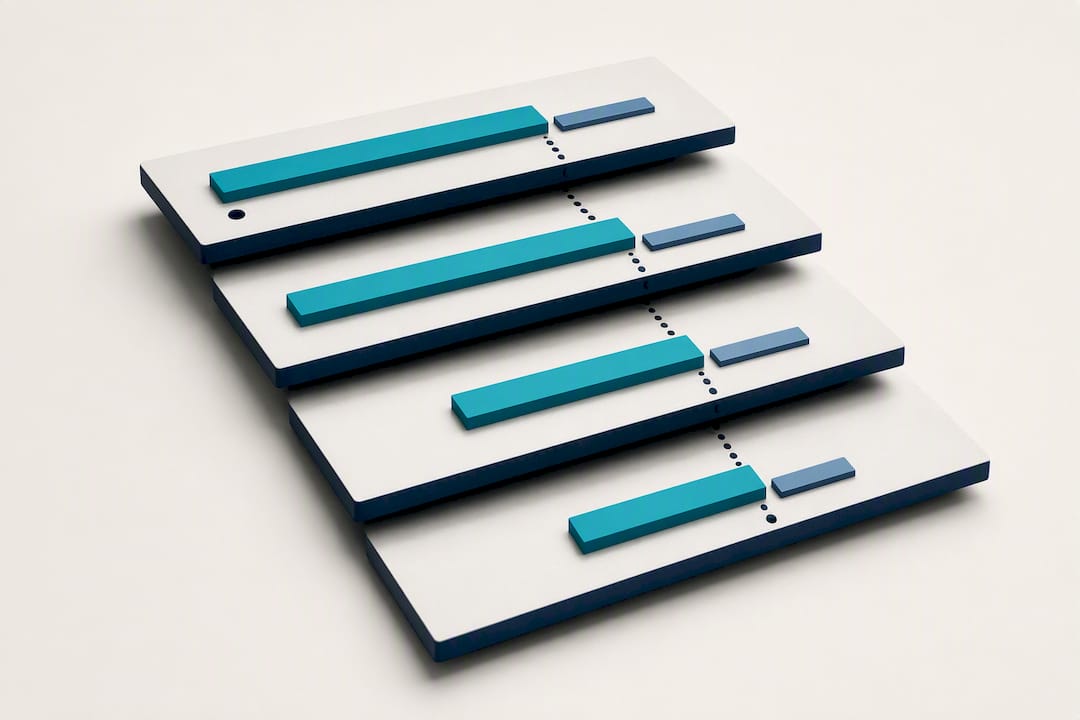
A trace follows a single request across every service it touches, built from a chain of timed spans. Each span records a start time, a duration, and metadata about one unit of work; strung together, they form a waterfall that shows which span ate the most time. That waterfall view is the fastest way to answer “why is checkout slow” when the answer isn’t obvious from a single service’s logs.
Trace anatomy in practice:
- A trace ID ties every span in one request together, end to end.
- Parent-child relationships show which service called which, and in what order.
- Span attributes (HTTP status, database query, user tier) give context without needing a separate log lookup.
Capturing every trace at scale is expensive, both in storage and in the overhead of instrumentation itself, so most teams sample.
Traces earn their keep in three scenarios: debugging latency across microservices, mapping which downstream dependency is actually failing, and confirming request flow looks right immediately after a deploy.
Logs, Metrics, and Traces Side by Side
Here’s the quick reference worth pinning to a runbook, since the fastest incident responders check the right signal first instead of scrolling through all three.
| Purpose | Data Type | Cardinality | Storage Cost / Retention | Best Use Cases | |
|---|---|---|---|---|---|
| Metrics | Detect trends, trigger alerts | Numeric time series | Low to moderate (bounded by labels) | Cheap, long retention (months) | Dashboards, SLOs, automated alerting |
| Logs | Explain what happened and why | Discrete timestamped events | High (unique per event) | Moderate, tiered by level | Root cause analysis, audits, stack traces |
| Traces | Show where time went across services | Structured spans with timing | High, usually sampled | Expensive if unsampled | Latency debugging, dependency mapping, post-deploy checks |
During an incident, that “cardinality” column is really telling you what’s cheap to check first. Metrics are cheap and fast, so check them first. Traces narrow the search. Logs close it out.
How Logs, Metrics, and Traces Work Together
None of the three signals is sufficient alone, and treating them as separate tools instead of one correlated system is where most observability setups fall short. The standard framing holds up well in practice: metrics tell you something is wrong, traces show where, and logs explain why.
A typical investigation runs like this:
- An alert fires on
error_rate p95exceeding a threshold for the checkout service. - You pull traces from that time window and find that most of the slow spans point to a single downstream call, the inventory service.
- You pivot to logs filtered by that service and the matching
trace_id, and find a stack trace showing a connection pool exhausted error.
That pivot from trace to logs only works if the same trace_id shows up in both places, which means it has to be propagated through your code and injected into every log statement, not just attached to spans. Consistent service naming and synchronized timestamps across your fleet matter just as much. If two services disagree on clock time by even a few seconds, correlating events across them becomes guesswork.
This is exactly the gap OpenTelemetry was built to close. It standardizes instrumentation and context propagation across all three signal types, and its collector pipeline gives you one place to enrich, batch, and route data to your backend of choice instead of wiring each service’s exporters by hand.
Pro Tip: Before you buy or build anything else, confirm your logging library can accept and emit the current span’s trace context automatically. Most OpenTelemetry language SDKs support this out of the box, and it’s the single highest-leverage change you can make to your correlation setup.
When to Reach for Each Signal
Three prompts cut through most of the indecision during an incident or a design review:
- “How many, how often?” Reach for a metric.
- “Where did it happen, which step?” Reach for a trace.
- “Why did it happen, what was the state?” Reach for a log.
Instrumentation order matters as much as the signal choice. Add metrics first, since they’re cheap and cover alerting and SLOs immediately. Add structured logs second, since they’re the fastest correlation win once trace_id propagation is in place. Add distributed tracing once requests genuinely cross service boundaries. A monolith rarely needs tracing on day one.
Overlaps are normal and not a sign you’re doing it wrong. If a value like queue_wait_ms matters both as a trend and as a per-request detail, emit it as both a span attribute and a metric. They serve different questions even when they carry the same number.
Sampling policy should differ by signal, and applying the same rule to all three is a common mistake:
- Sample traces aggressively; a representative slice is usually enough.
- Don’t randomly sample logs; filter and redact instead, since you rarely know in advance which log line will matter.
- Control metric cardinality at the label level, not by dropping data points.
Implementation Considerations: Instrumentation, Storage, and Cost
Getting the data model right matters more than which vendor you pick. A few decisions determine whether your three signals stay correlated or drift apart:
- Attach
trace_idto logs through your logging library’s context propagation, not by manually threading it through every function call. - Use auto-instrumentation for standard frameworks (HTTP clients, database drivers) and reserve manual spans for business logic worth tracking on its own, like a payment authorization step.
- Bound metric label cardinality deliberately; a label with unbounded values (user ID, session ID) belongs in a log or a trace attribute, never in a metric.
- Route everything through a collector pipeline for batching and enrichment rather than exporting directly from each service.
Pro Tip: Set retention windows by signal, not by a single blanket policy. Traces are typically sampled and cheaper to keep briefly; metrics are cheap to keep for a year; logs are the expensive one, so tier them by level and prune DEBUG output aggressively.
A 30/90/180-Day Roadmap to Working Observability
- Days 1 to 30: Export core metrics (
latency,error_rate,request_count), enable structured logging on critical services, and add request IDs everywhere. - Days 31 to 90: Instrument distributed tracing on your top request flows, tune trace sampling, and wire
trace_idpropagation between traces and logs. - Days 91 to 180: Define SLOs against your metrics, tighten alert thresholds to cut noise, optimize retention costs, and automate the runbooks your on-call team runs most often.
Track this against MTTR, alert volume, and SLO compliance. Teams that finish this roadmap typically see fewer false-positive pages within the first two phases alone.
Correlate Every Signal in One Place With Opsphere
Building the pipeline above is worth it, but most teams still end up switching between five tabs to connect a metric alert to a trace to a log line. Opsphere unifies operational context across AWS, Kubernetes, observability tools, and CI/CD pipelines so that correlation isn’t a manual pivot exercise anymore.
Instead of hand-tracing trace_id values across multiple dashboards, AI agents can pull the relevant metrics, traces, and logs into a single investigation view, which cuts the time between “an alert fired” and “we found the root cause.” For platform teams already juggling too many tools, that consolidation is often the difference between a five-minute investigation and a fifty-minute one. If your stack already emits structured logs and traces through OpenTelemetry, connecting it to a unified operational layer is the natural next step. Visit the Opsphere web client to see how a unified query interface handles a live incident, or request a demo to walk through your own signal setup with the team.
Sources
- Logs vs Metrics vs Traces - Engineering Fundamentals
- Logs vs Metrics (and Errors): When to Use Each | Sentry Blog
- What Is the Difference Between Tracing and Logging? | Baeldung on Computer Science
- OpenTelemetry Signals Overview: Logs vs Metrics vs Traces · Dash0
- Three pillars of observability: Logs, metrics and traces
FAQ
What Is the Difference Between a Log and a Metric?
A metric is a compressed numeric measurement built for trends and alerting, while a log is a discrete, timestamped event record that carries the detailed context, like a stack trace, needed to explain what happened.
What’s the Difference Between Logs and Traces?
A log records a single event within one service, while a trace follows one request’s full path across multiple services using connected spans, which is why traces are better for cross-service latency debugging.
What Are the Three Types of Observability?
The three pillars are metrics (aggregate numeric trends), logs (detailed event records), and traces (the end-to-end path of a request across services), and together they cover detection, location, and explanation during an incident.
What Are the Three Types of Logs, by Common Convention?
Teams typically group logs by purpose: application logs (business logic and errors), system or infrastructure logs (host and container health), and audit logs (security and access events), each often carrying different retention rules.
Do I Need Distributed Tracing If I Only Run a Few Services?
Not immediately. Metrics and structured logs with request IDs cover most single-service or lightly distributed setups; add tracing once requests routinely cross three or more service boundaries and latency debugging becomes guesswork without it.
Recommended
This article is provided for general informational purposes only and does not constitute professional, legal, security, or compliance advice. Please evaluate recommendations against your organization’s specific environment and requirements.