Blog
Latest articles, guides, and updates.
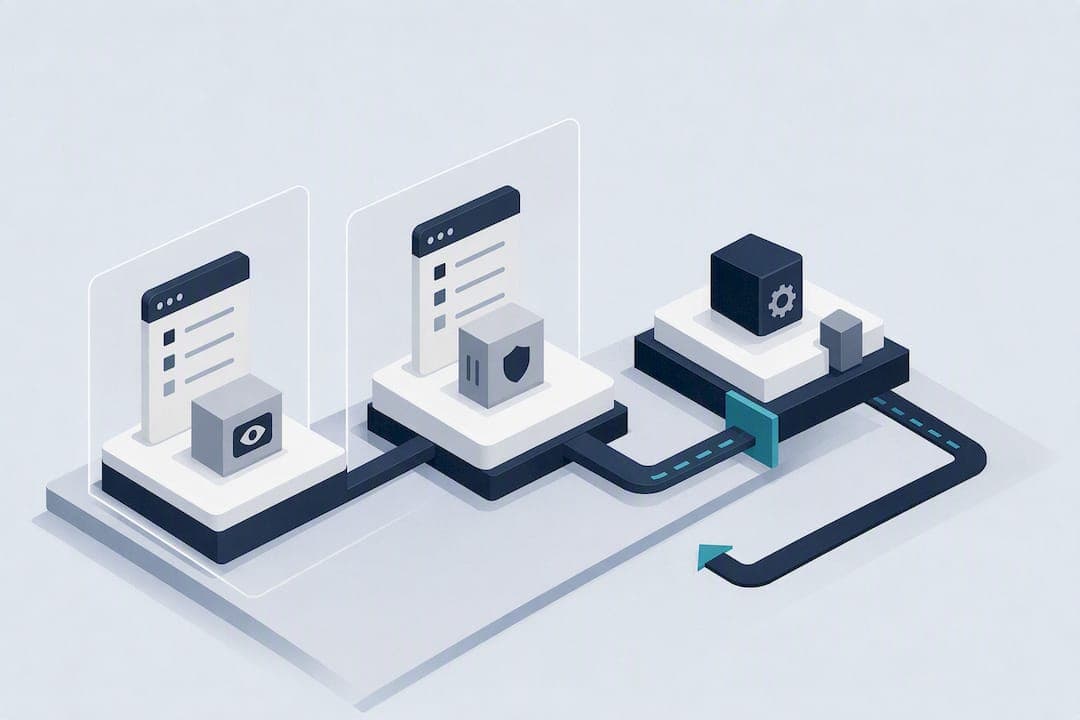
Safe Automation for SREs: From Read Only Agents to Scoped Remediation
Safety-first automated incident response for SREs. Follow phased steps—observe, suggest, scoped automation—to validate agents, enforce gates, and run...
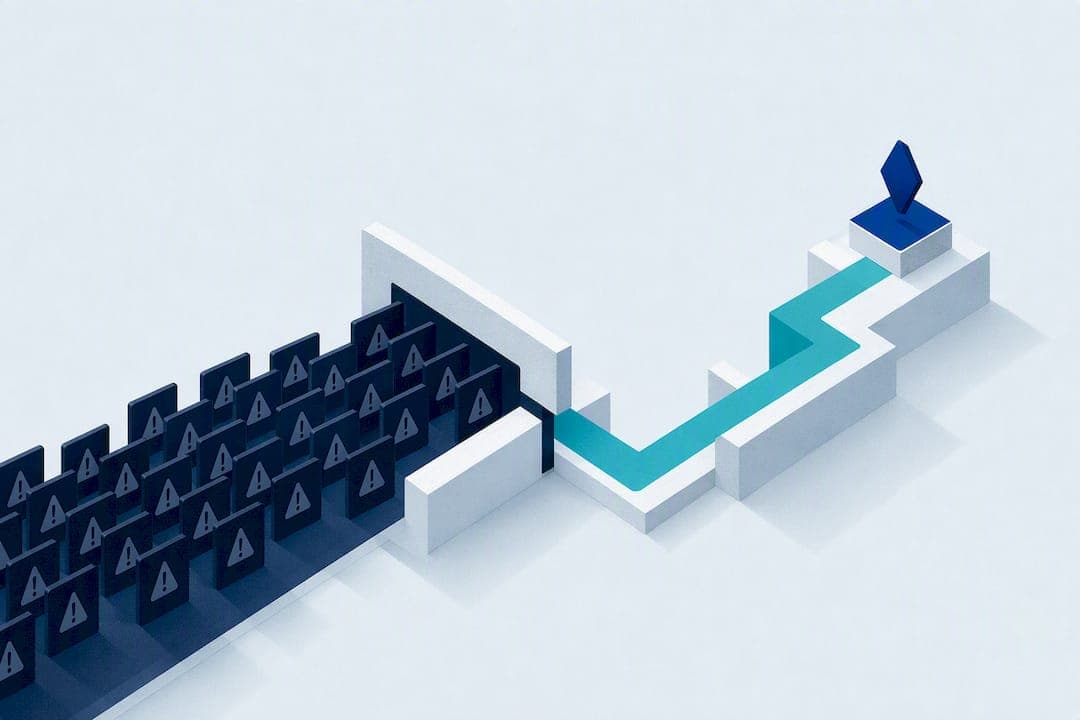
Measure First, Automate Alert Fatigue for Healthcare, SOCs, DevOps
Explainer for healthcare, SOCs, and DevOps on diagnosing alert fatigue. Learn how to measure noise, prioritize alerts, and use safe AI triage.
Start With a One-Page Playbook: Runbook vs Playbook for SREs
Practical runbook vs playbook guidance for DevOps, SRE, and platform teams. Start with a one-page playbook, add runbooks for repeat failures, and keep...
Save the First Hour: Blast Radius Analysis for SREs and Platform Teams
Practical blast radius analysis for SREs and platform teams. Use 15–30 minute scans, map graph reach to business risk, and avoid losing the first hour of...
Self Healing Infrastructure for SREs: Evidence Chains, GitOps Safety
Safety first playbook for SREs to deploy AI assisted self healing with evidence chains, declarative GitOps repairs, and reversible governance.
MTTR Reduction in 90 Days for SREs with Instrumentation and AI
A practitioner guide for SREs and platform teams: cut MTTR by prioritizing full-fidelity instrumentation, SLO-driven alerts, AI-assisted diagnosis, and a...
Draft First, Run in 30–60 Minutes: Blameless Postmortems for SREs
Run blameless postmortems that produce fixes: start with a draft, use scripted facilitation and clear owners, and cut prep time with a unified operational...
Small SRE Teams: 5–10 Runbooks for AI Observability via Terraform Native
Small SRE teams: adopt AI observability by unifying telemetry, mapping dependencies, and running 5–10 automations with Terraform native integration.